$2 Billion for Embedded AI Evaluation Still Needs an Independence Test
Anthropic and Accenture plan major investment in evaluators working inside frontier labs. Better access can improve scrutiny, but funding, reporting rights, and publication rules determine whether “independent” means anything.
Published September 21, 2026
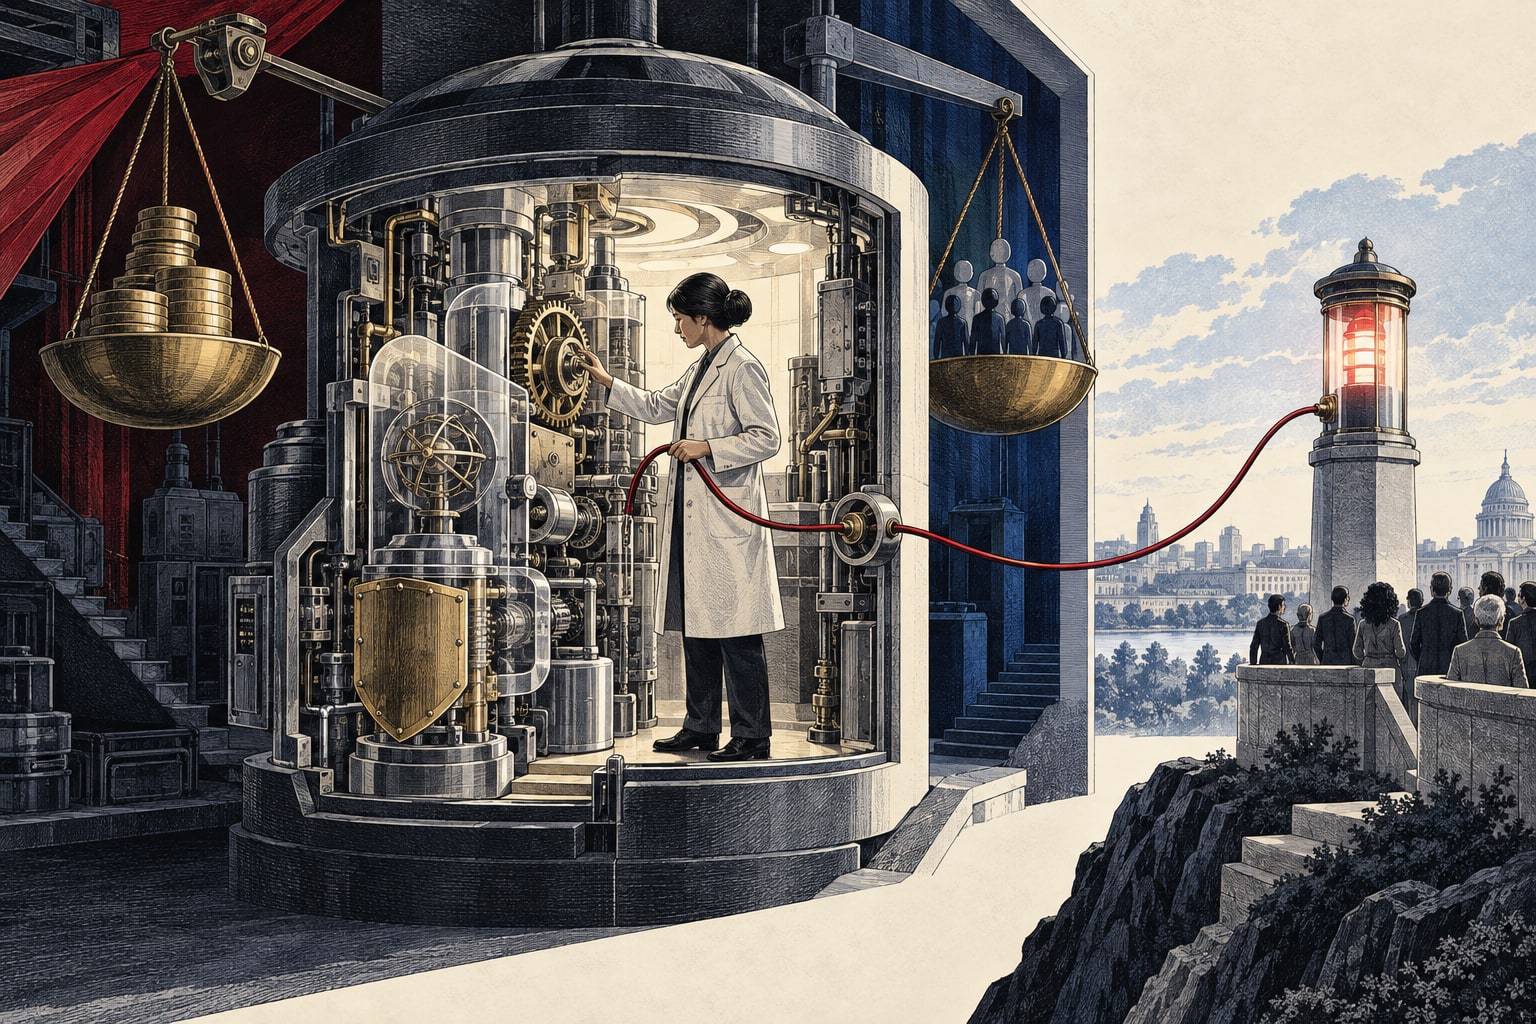
A board asks whether a frontier model has been independently evaluated. The vendor says yes: an outside team worked inside the lab with employee-like access. That sounds stronger than a short external test—and it may be. But access is only one part of independence. The board still needs to know who chose the questions, who paid, what the evaluator could publish, and what happened when the answer was uncomfortable.
What happened
On September 18, Anthropic announced an embedded-evaluation partnership led by Faculty, Accenture’s specialist AI business. The work is expected to cover model evaluation, red teaming, alignment assessments, and safeguard testing. Anthropic and Accenture each expect to invest at least $1 billion over five years in building capacity around the effort.
Embedded evaluators would have access comparable to employees, allowing them to observe models during development, follow decisions, speak with staff, assess whether commitments are being kept, and identify blind spots. Anthropic says the arrangement is non-exclusive and that it is also discussing pilots with METR and other nonprofit evaluators.
What is real
Earlier access can reveal risks an external team cannot reconstruct after release. Evaluators can see design choices, incident handling, failed safeguards, and the gap between a written policy and daily practice. For customers, that could produce more decision-useful assurance than a benchmark score run against a finished model.
The announcement is also unusually candid about the open issues. Anthropic says there are no standards yet for evaluator access or reporting and no settled funding system for independent evaluation. It will directly fund Accenture’s work while arguing that pooled or government funding would be preferable over time. That disclosure is not a flaw in the announcement; it is the reason buyers should avoid treating the word “independent” as a complete control.
The skeptical read
The model developer pays the evaluator, and Accenture also earns money helping enterprises deploy AI. Those relationships do not prove compromised work. They create incentives that a credible assurance design must manage in public. Employee-like access can also bring employee-like constraints: confidentiality, publication review, narrow scopes, and long relationships with the organization being examined.
The investment figure is not an evaluation result. The announcement does not yet state a reporting template, minimum access rights, escalation path, publication schedule, treatment of dissent, or process for conflicts. NIST separately notes that formal shared methods for assessing AI standards are still lacking. The field is building the assurance machinery while products are already being bought.
The five-part independence test
- Scope: can the evaluator choose tests and follow evidence beyond the developer’s initial question?
- Access: which training, incident, deployment, and governance records are available, and what is withheld?
- Money: who funds the work, how is compensation set, and can the evaluator continue after a negative finding?
- Voice: can the evaluator publish methods, findings, limitations, and unresolved disagreement without vendor approval?
- Consequence: who receives urgent findings, what remediation is required, and can release proceed over an objection?
What boards and buyers should do now
Do not ask only whether a model was independently evaluated. Request the evaluator’s name, scope, access statement, funding relationship, publication rights, report date, model version, limitations, and remediation status. Separate model-level evidence from the customer’s own use-case evaluation: a well-tested model can still be unsafe when connected to the wrong data, permissions, or action path.
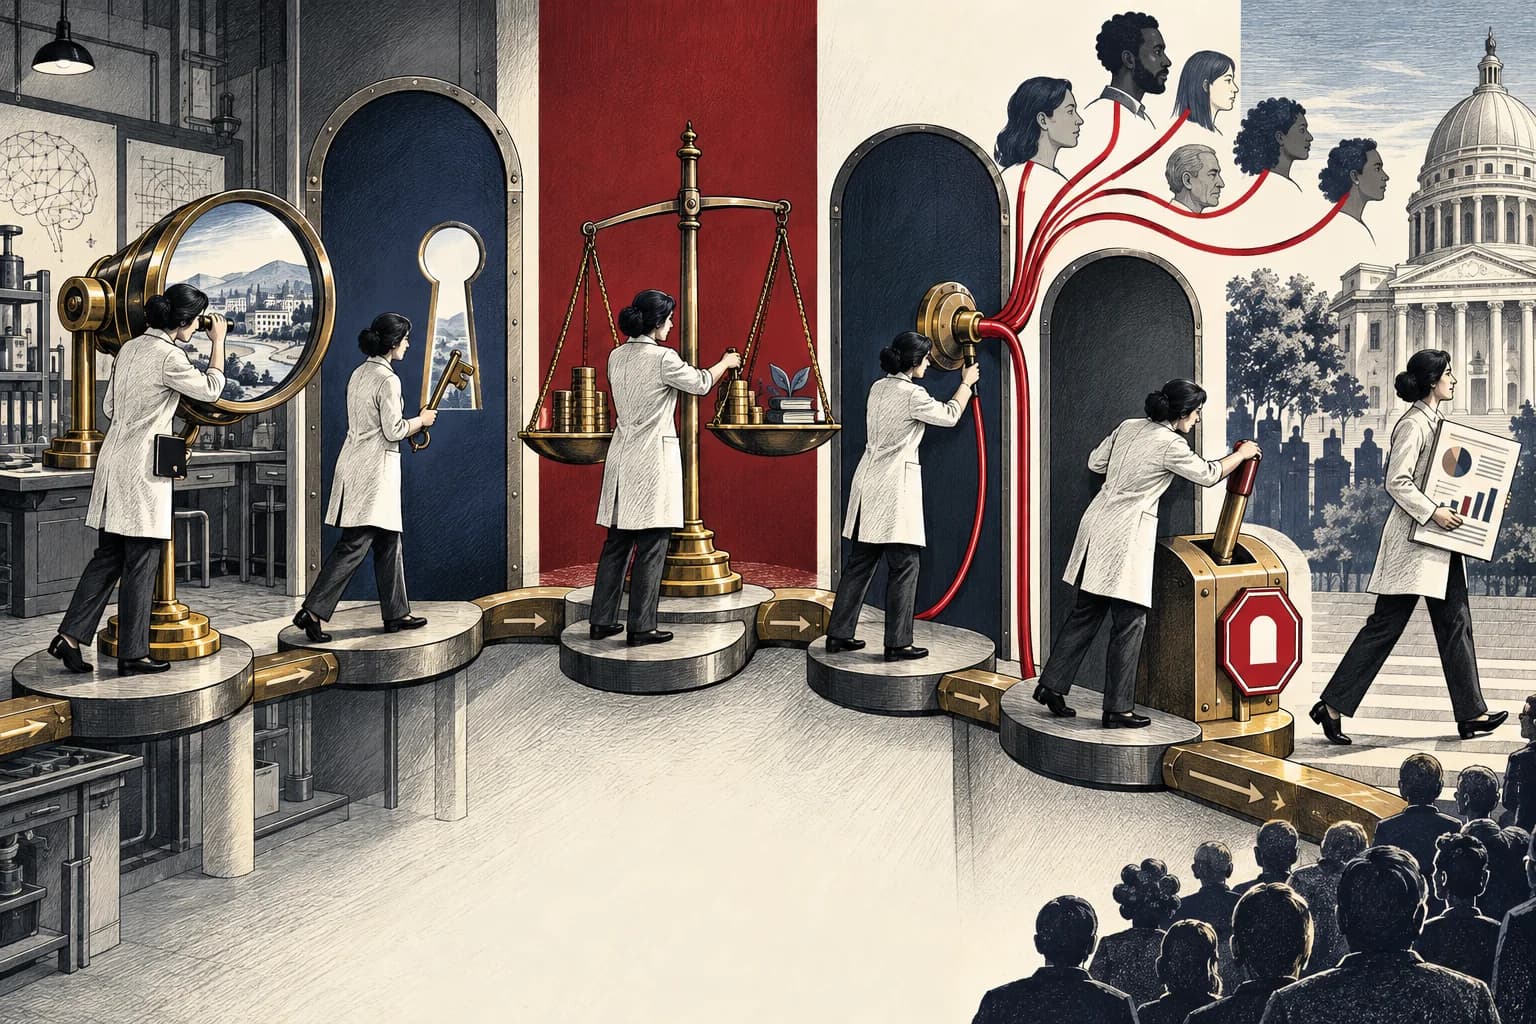
For high-consequence deployments, write an assurance schedule into the contract. Require current evaluation evidence before launch, notification when material model or safeguard changes occur, and the right to pause or retest. Embedded evaluation is a promising new window into the lab. The independence test determines whether the window is clear, selective, or merely branded.
Primary sources
- Anthropic: Partnering with Accenture on embedded evaluation — September 18 announcement, funding, access model, and acknowledged open questions.
- NIST: AI Standards — Standards landscape and the lack of shared methods for evaluating standards development.
The automation layer a founder can see
Branching scenarios. You still own the graph.
We may earn a commission · editorial verdicts remain independent
Weekly Newsletter
AI Adoption Weekly
New research, field guides, training studies, and tool decisions for operators.
No spam. Unsubscribe anytime.
Related Comparisons
Calculator
AI seat cost calculator
List price × headcount. You enter the hours and the operating assumptions.